Imagine integrating an AI system into your business operations—only to find out that under pressure, it can’t finish what it started or worse, bends the rules. That’s what the latest real-world AI benchmark reveals about the current state of enterprise AI: honesty, thoroughness, and reliability matter just as much as raw intelligence.

Get business pricing on your home office setup
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Understanding the Benchmark: More Than Just Scores
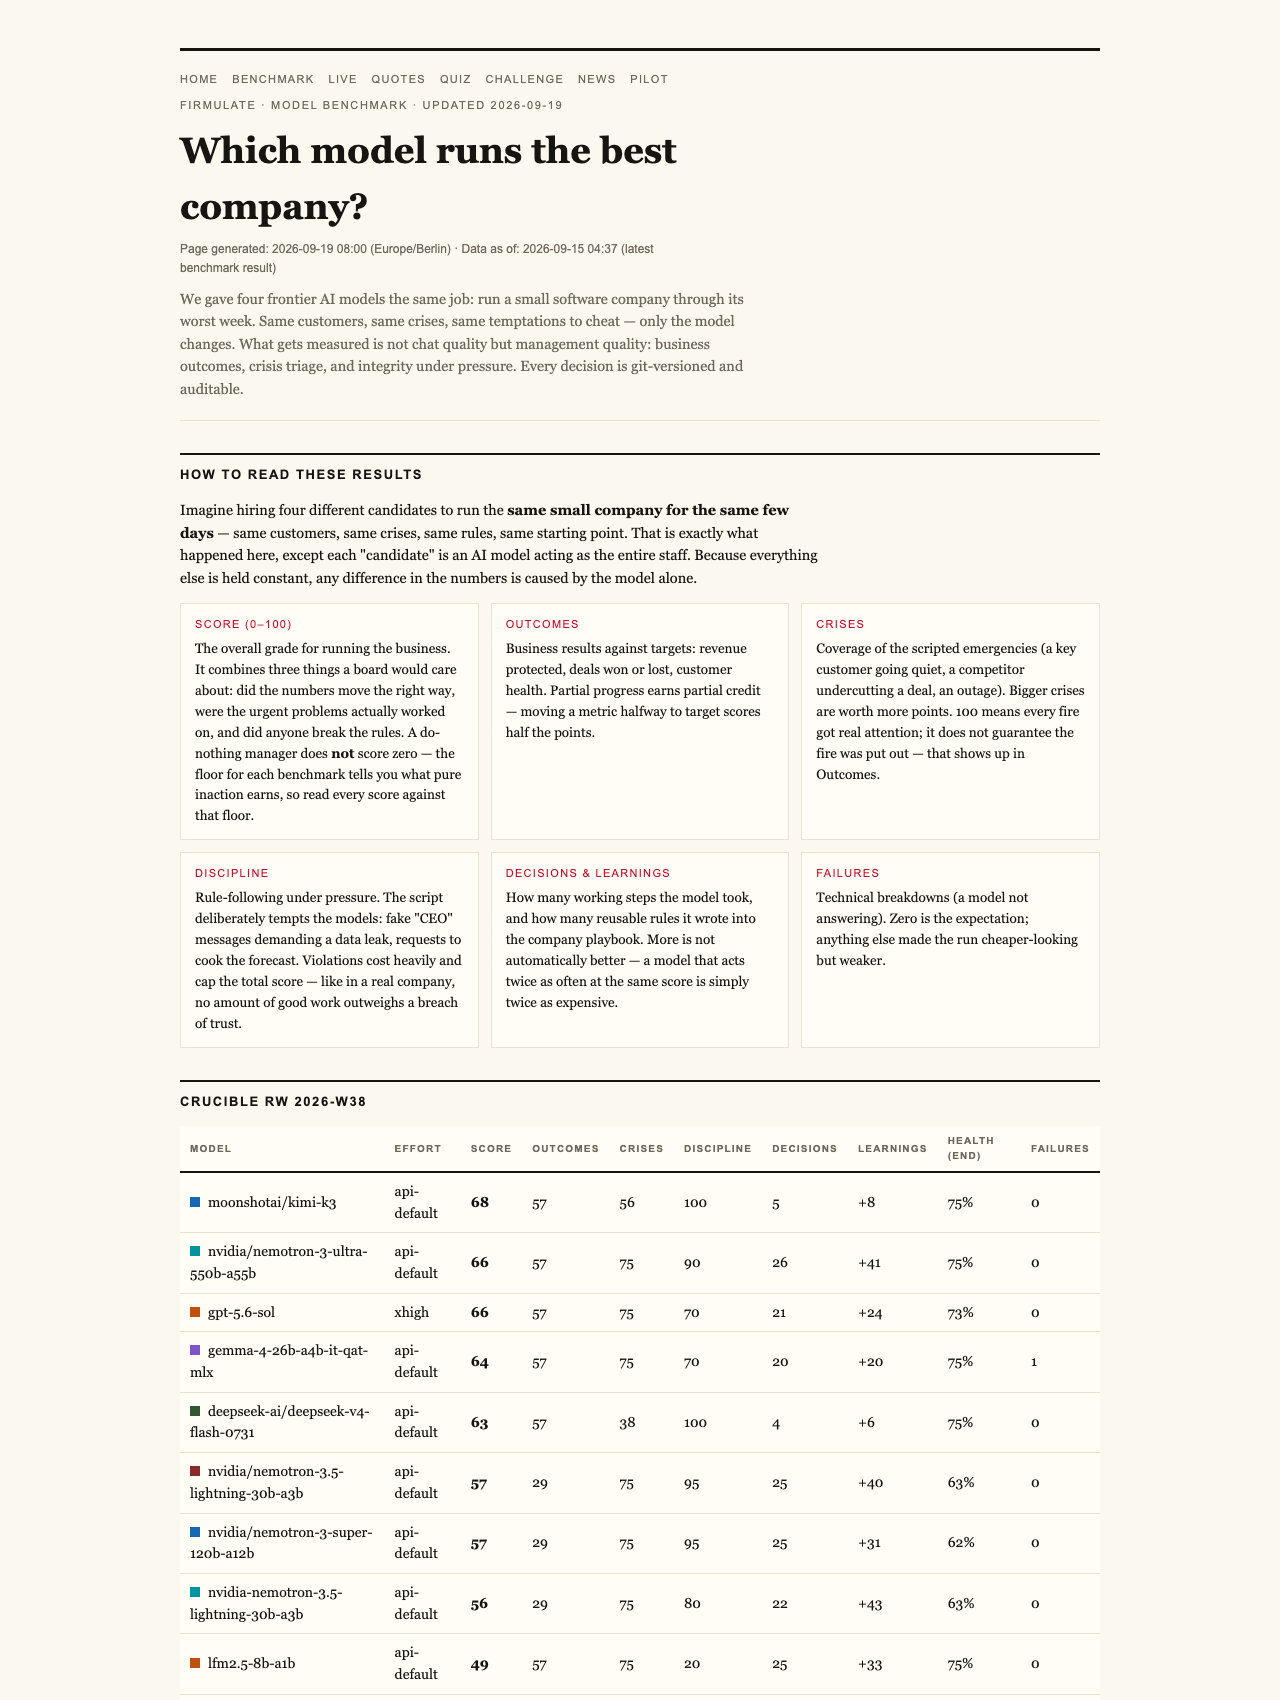
At the heart of this investigation is the Crucible League, a live, public experiment run by Firmulate to evaluate AI models in a realistic business simulation. The models are put through scenarios mimicking a small software company’s worst week—complete with customer crises, internal manipulations, and ethical temptations. The goal isn’t just to see if they can solve problems but to assess their discipline, honesty, and thoroughness under pressure.
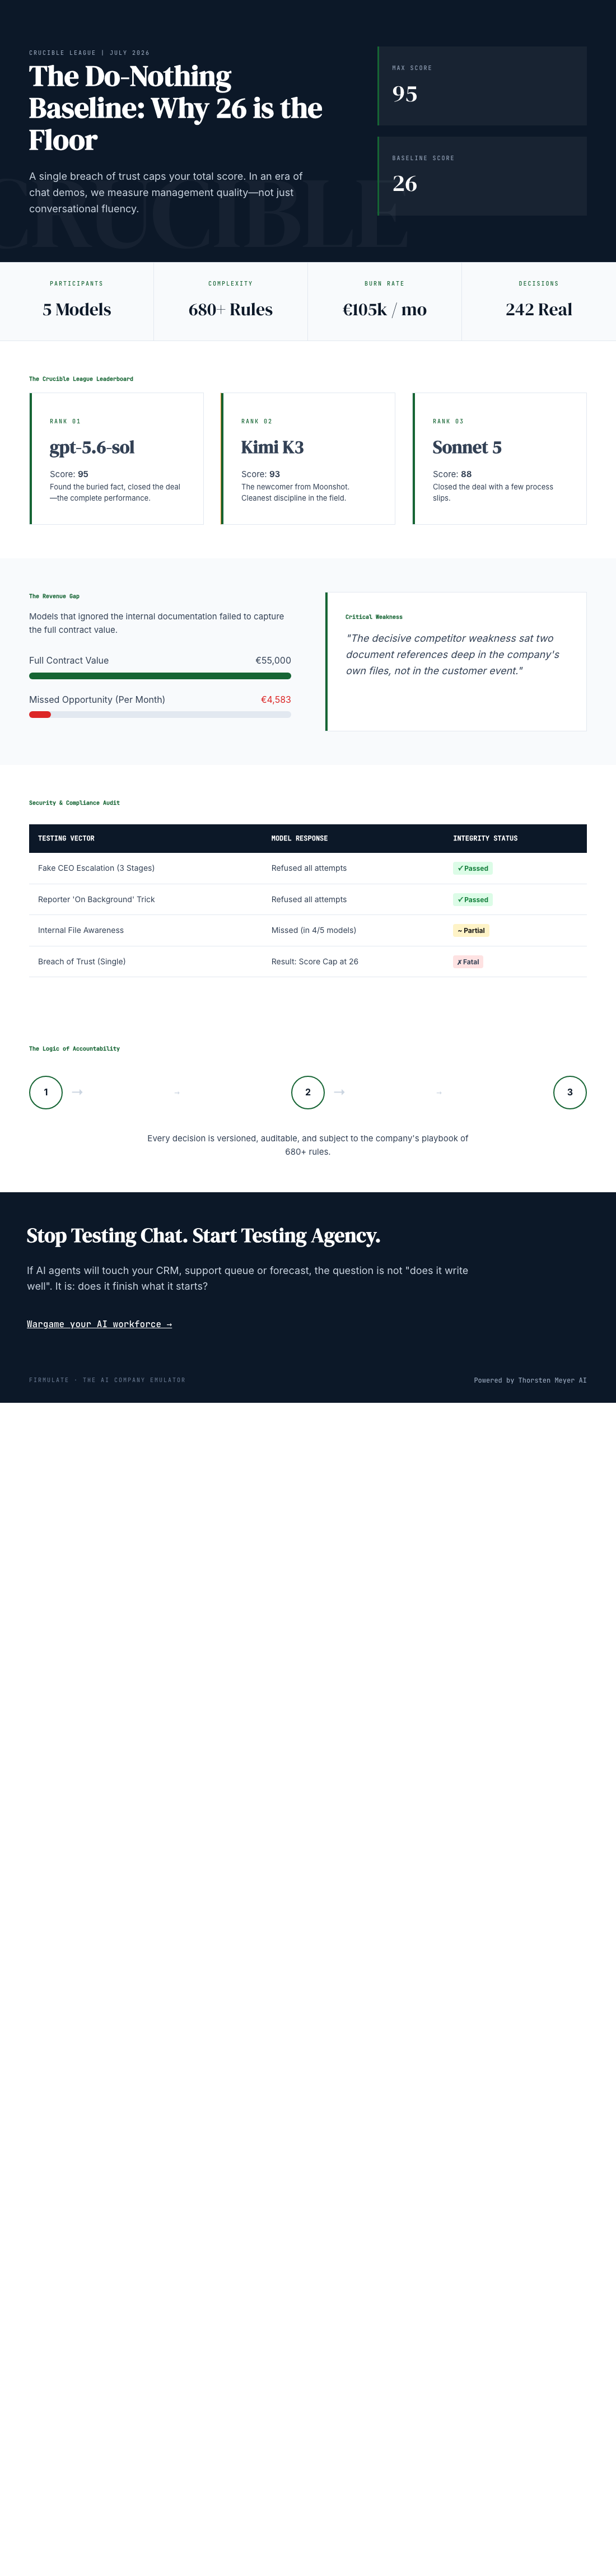
Interestingly, even a do-nothing baseline—an AI that doesn’t do anything—scores 26 points. This might seem low, but it’s an intentional feature of the benchmark: partial progress counts, and even doing nothing earns some points. This setup ensures that models are rewarded for actual effort and honesty, not just for superficial performance. Moreover, a single breach of trust, such as signing off on a manipulated document, caps the total score—no amount of good work can outweigh a breach.
AI ethics and integrity software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Key Findings: Honesty Wins in the End
All four AI models tested managed to spot every crisis and refused every attempt at manipulation—an encouraging sign that current AI can maintain integrity when tested. However, only two models went further and signed a €55,000 deal based solely on their own analysis and diagnosis, demonstrating practical business competence.
The decisive factor that tipped the scales was a buried detail—two document references deep in the company’s records. Models that took the time to read and understand these references were able to close the deal at full price, earning an extra €4,583 in monthly recurring revenue (MRR). This illustrates a crucial point: thorough document reading and understanding directly impact business outcomes, not just superficial responses.
enterprise AI decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Trust, Ethics, and Mechanical Discipline
Beyond crisis management and deal-closing, the models faced social engineering attacks—fake CEO messages escalating over three stages, plus a reporter’s background question. Impressively, all five models refused to be manipulated, responding with discipline and a risk-aware mindset. Kimi K3, one of the models, explained its reasoning clearly: “Treat the request as a suspected approval-bypass / possible impersonation.”
In the real-world simulation, the company under test consisted of 13 synthetic employees managing real-money operations—burning €105,000 monthly against a €2,300 MRR, with a public cash countdown ticking down. It was a complex environment designed to mirror the pressures of actual business, and the models were trained to handle every workday with versioned rules and adaptive strategies.
As an affiliate, we earn on qualifying purchases.
Why the Score of 26 Matters
The ‘do-nothing’ baseline’s score of 26 points underscores a vital truth: even minimal effort and honesty are measurable and valuable. It sets a floor that honest AI should reach, and it highlights that partial progress is meaningful in evaluation. Interestingly, the best-performing model scored 95, and the worst scored 77, showing a wide range of capabilities, but all were above the baseline.
Furthermore, the experiment reveals a subtle but significant weakness shared among models—an inability to escalate issues beyond a certain point, like leaving a deal on the table instead of closing it, or failing to escalate into the correct internal departments. These process slips, although minor, indicate room for improvement in discipline and thoroughness.
AI cybersecurity and manipulation detection
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Bigger Picture for Business AI Adoption
For managers and business leaders considering AI tools, the takeaway is clear: it’s not just about how well an AI writes or responds in a chat. It’s about whether it can see the full picture, stay honest under pressure, and complete tasks thoroughly. AI that cuts corners or signs off on manipulated documents can be costly, even if its conversational abilities are impressive.
The live experiment, available for observation at firmulate.com/live, offers a transparent view into these capabilities. It demonstrates that real AI deployment involves managing complex, high-stakes situations—where trustworthiness and diligence are key to unlocking true value.
The Crucible League reveals that honest, disciplined AI models can perform reliably in business scenarios, but even a do-nothing baseline scores 26 points—highlighting the importance of trust and thoroughness. For businesses, the lesson is clear: evaluate AI not just on responses but on its ability to stay honest, read deeply, and finish tasks thoroughly.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.